01Intelligent Offloading
DePIN-Router
AI-Driven Intelligent Workload Offloading Model
Mechanism
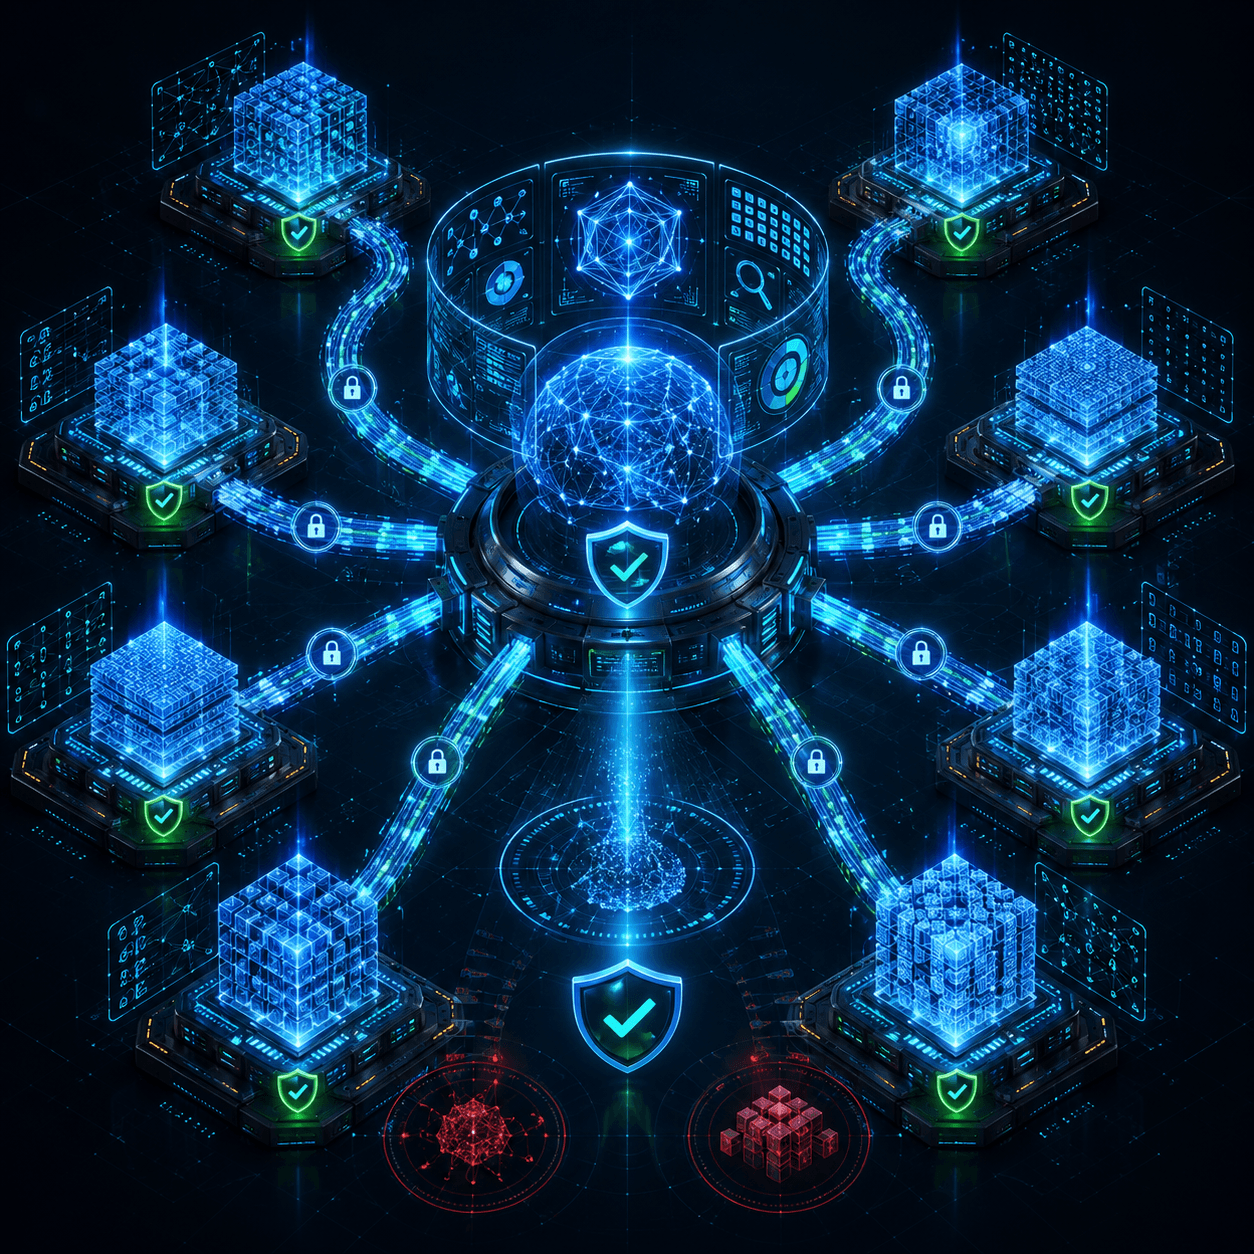
Ingests continuous telemetry streams — VRAM latency, CUDA core thermal metrics, network jitter, and matrix-multiplication throughput — from globally aggregated nodes.
Token / Data Scale
Processes over 1.5 Trillion time-series telemetry tokens to continuously train an RL-driven Mixture-of-Experts (MoE) model capable of dynamic, microsecond-level AI task partitioning across heterogeneous hardware.